Text set in serif type with a dotted bar in the margin was drafted by an LLM (claude-opus-5) and sometimes reviewed by the author. The rest is the author's own. How to read this site
schedopt_v5_confirm
20260727_203158_schedopt_v5_confirm · complete · published 2026-07-28 · seed 43000
part of investigation alpha-curriculum → schedule-opt → schedopt-v5
Intent
The v5 finalists, prior winners, incumbent, and flat controls are re-measured on one fresh paired seed cohort under the frozen crossing-quantile instrument.
Hypothesis
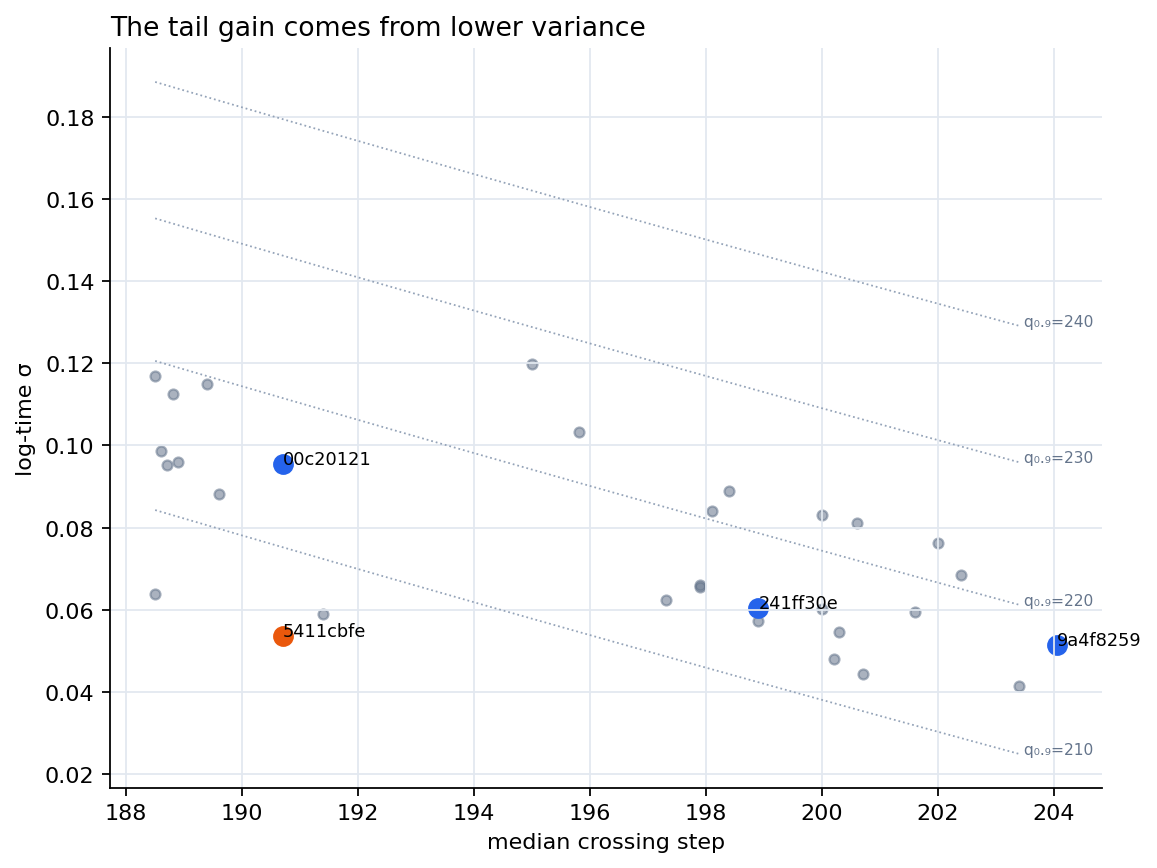
The best v5 schedule retains a lower held-out q0.9 than the v4 incumbent and the best flat control because its crossing-time variance is lower, despite no improvement in its median.
Setup
| arm | data regime | datasets | iters/dataset | epochs/dataset |
|---|---|---|---|---|
| ascend3 | fresh-dataset-per-stage | 15 | [25, 50] | [0.02, 0.04] |
| cand3 | fresh-dataset-per-stage | 16 | 25 | 0.02 |
| flat_1_6 | single-dataset-recycled | 1 | 400 | 0.33 |
| flat_1_8 | single-dataset-recycled | 1 | 400 | 0.33 |
| free-00c20121 | fresh-dataset-per-stage | 25 | [10, 20, 30, 120] | [0.01, 0.02, 0.03, 0.1] |
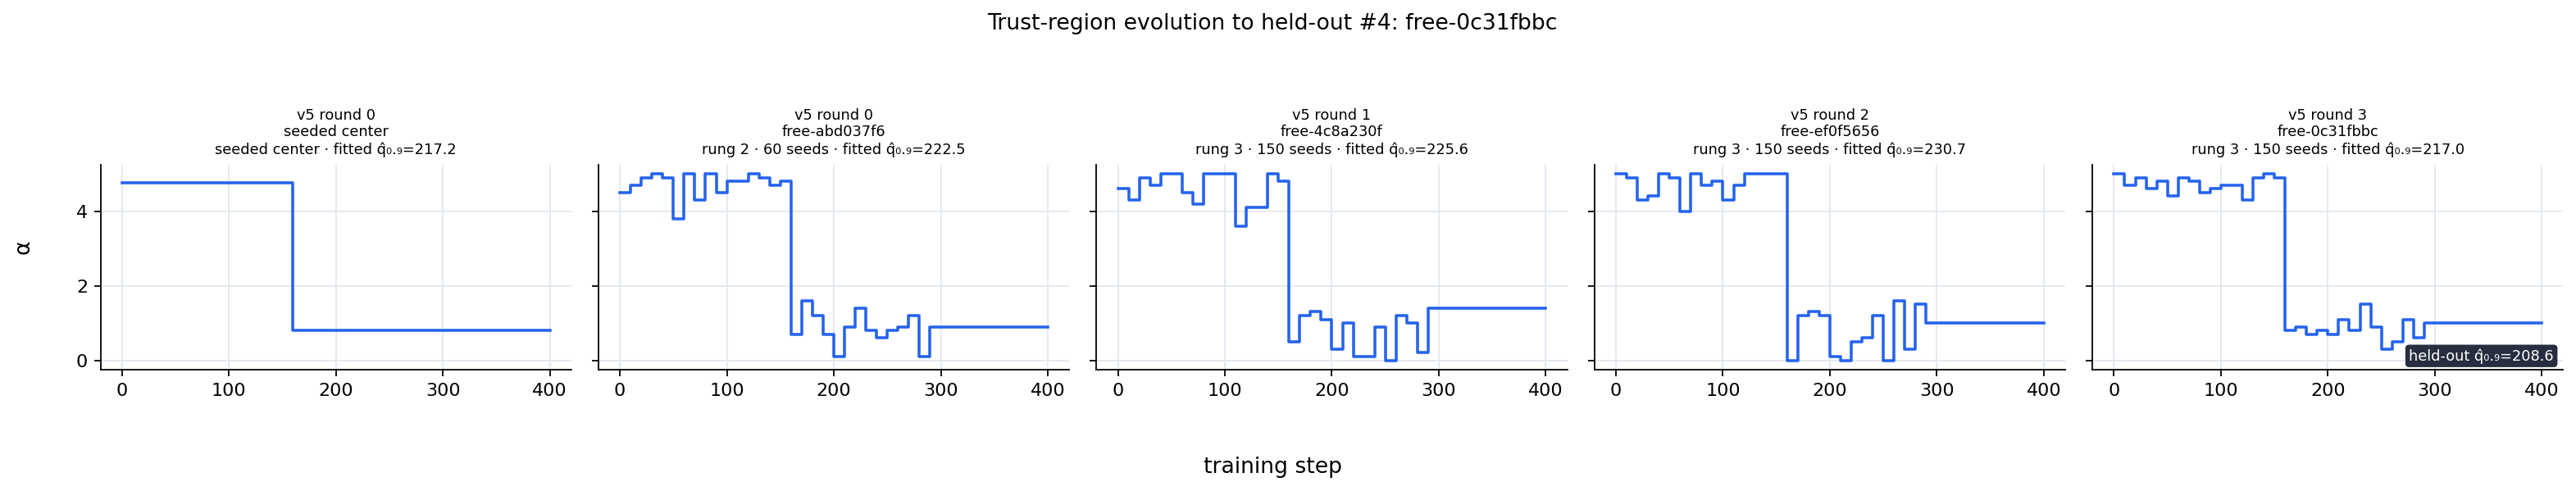
| free-0c31fbbc | fresh-dataset-per-stage | 29 | [10, 20, 110] | [0.01, 0.02, 0.09] |
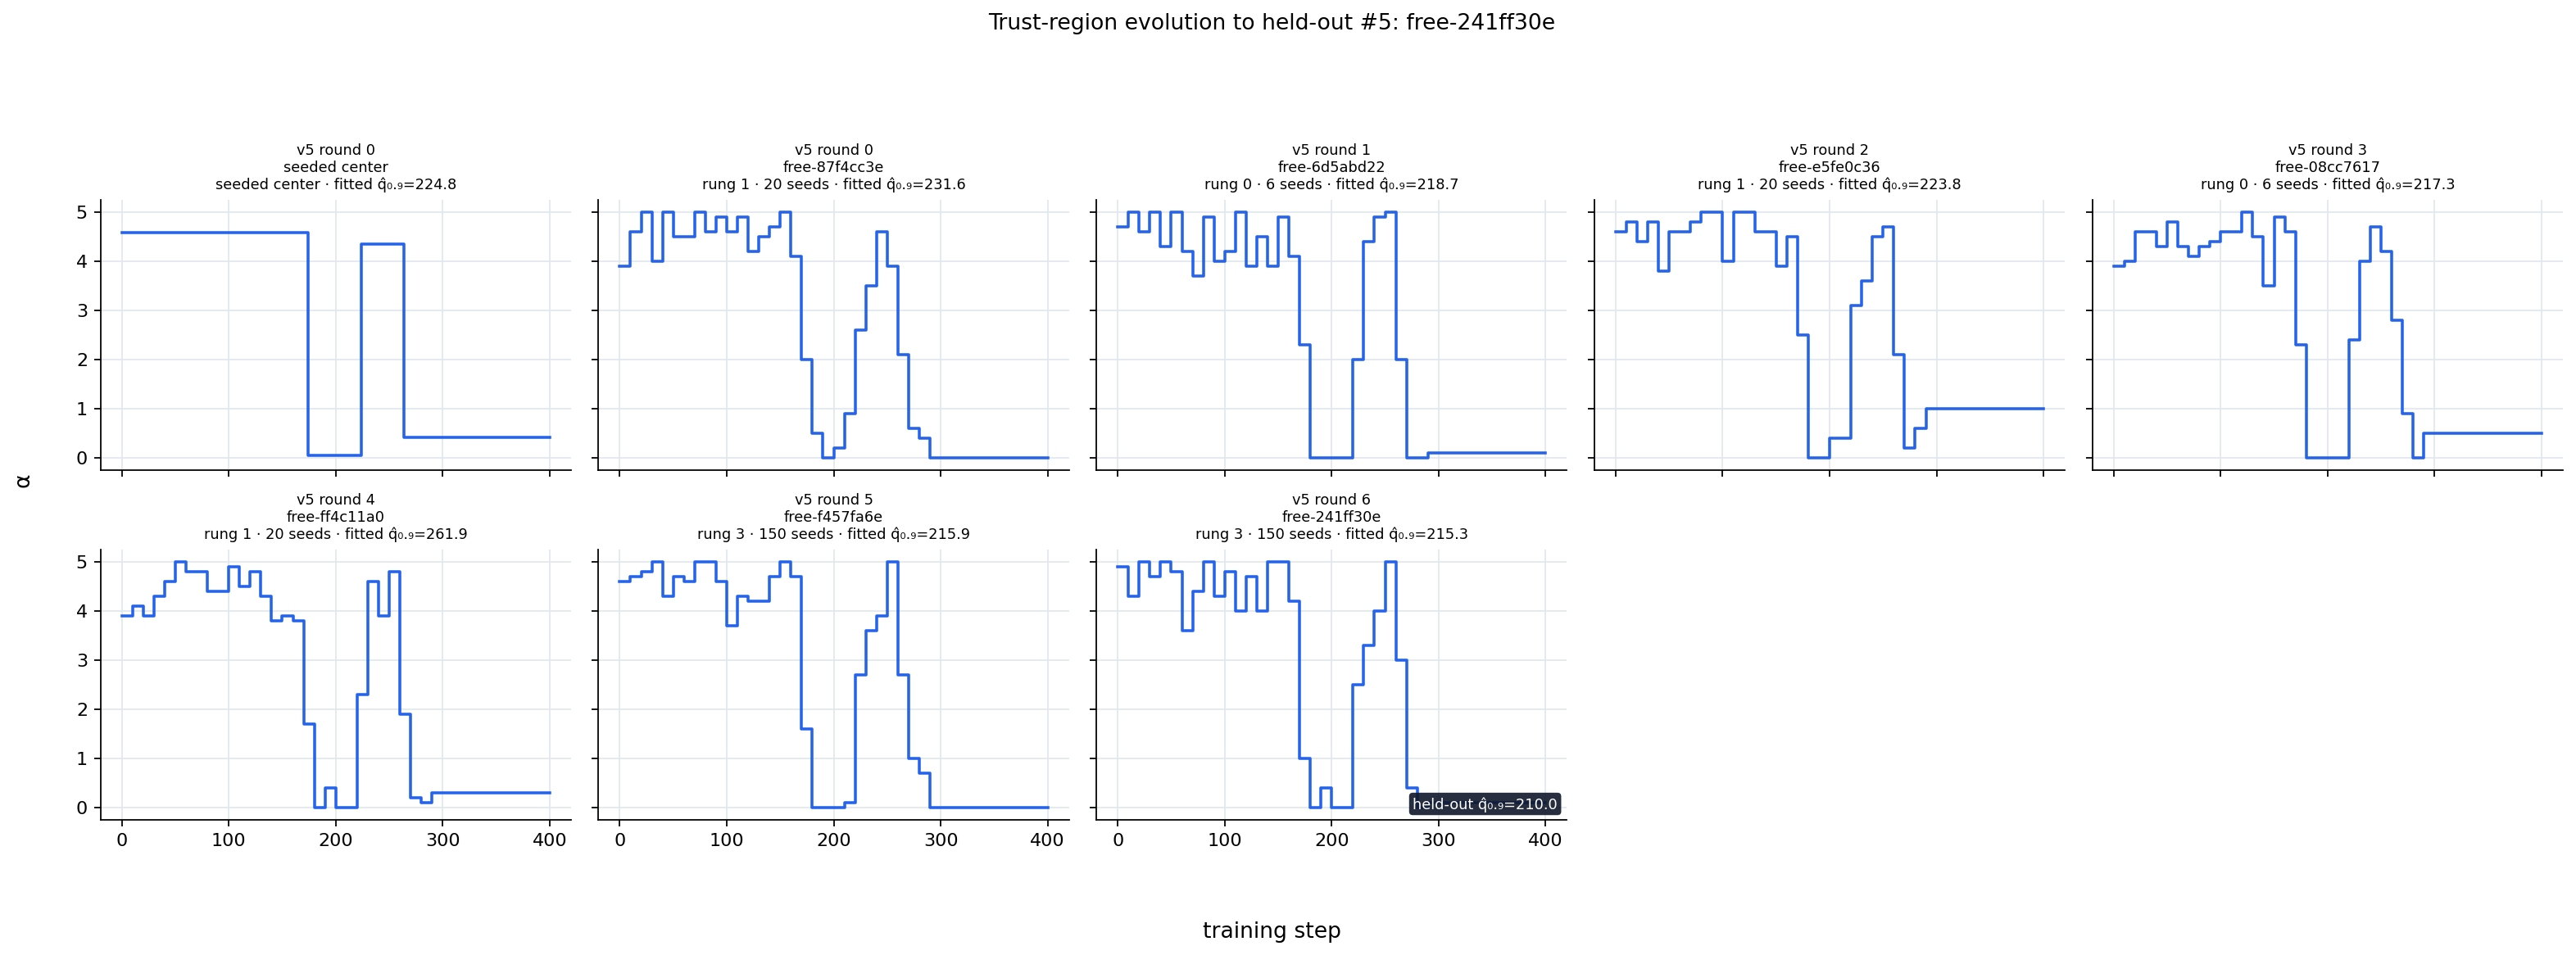
| free-241ff30e | fresh-dataset-per-stage | 28 | [10, 20, 110] | [0.01, 0.02, 0.09] |
| free-5411cbfe | fresh-dataset-per-stage | 3 | [100, 140, 160] | [0.08, 0.12, 0.13] |
| free-6217439f | fresh-dataset-per-stage | 27 | [10, 20, 120] | [0.01, 0.02, 0.1] |
| free-82f9c620 | fresh-dataset-per-stage | 30 | [10, 110] | [0.01, 0.09] |
| free-9a4f8259 | fresh-dataset-per-stage | 27 | [10, 20, 110] | [0.01, 0.02, 0.09] |
| free-c667dd31 | fresh-dataset-per-stage | 29 | [10, 20, 110] | [0.01, 0.02, 0.09] |
| free-d56d6dda | fresh-dataset-per-stage | 26 | [10, 20, 110] | [0.01, 0.02, 0.09] |
| free-e059ed86 | fresh-dataset-per-stage | 30 | [10, 110] | [0.01, 0.09] |
| free-f457fa6e | fresh-dataset-per-stage | 26 | [10, 20, 30, 110] | [0.01, 0.02, 0.03, 0.09] |
| phi3star | fresh-dataset-per-stage | 15 | [25, 50] | [0.02, 0.04] |
| phi4star | fresh-dataset-per-stage | 15 | [25, 50] | [0.02, 0.04] |
Replicate this experiment
Get the code at this exact version:
git clone https://github.com/ClaireHobbs/imagining-syntax
cd imagining-syntax
git checkout 64b6149efa0f
pip install -e ".[dev]"
Download the config (experiment.yaml) and run:
imsyn exp run experiment.yamlChecks
PASS children_complete PASS replicate_coverage PASS schedule_total_matches_final_waypoint PASS instrument_consistent PASS objective_computable
Claims
| claim | source | expectation | Δ | seeds | verdict |
|---|---|---|---|---|---|
| headline | schedopt v5 publication design, frozen before held-out seed 43000 trained | free-9a4f8259 < free-5411cbfe on unseen_mismatch (crossing-time quantile) | +14.1 | — | rejected |
| variance_thesis | schedopt v5 publication design, frozen before held-out seed 43000 trained; full conjunction is in publication_analysis | top-three v5 median crossing time >= incumbent and top-three log-time sigma < incumbent | -0.0 | — | mixed median Δ +7.1 [+4.3, +8.9]; log-time σ Δ -0.006 |
| beats_best_flat | schedopt v5 publication design, frozen before held-out seed 43000 trained; publication_analysis selects the better flat | free-9a4f8259 q0.9 < best held-out flat (flat_1_8) | -121.7 | — | held |
| winner_curse | schedopt v5 publication design, frozen before held-out seed 43000 trained; top-ten mean is in publication_analysis | mean held-out minus in-sample q0.9 over the v5 top ten > 0 | -3.8 | — | mixed |
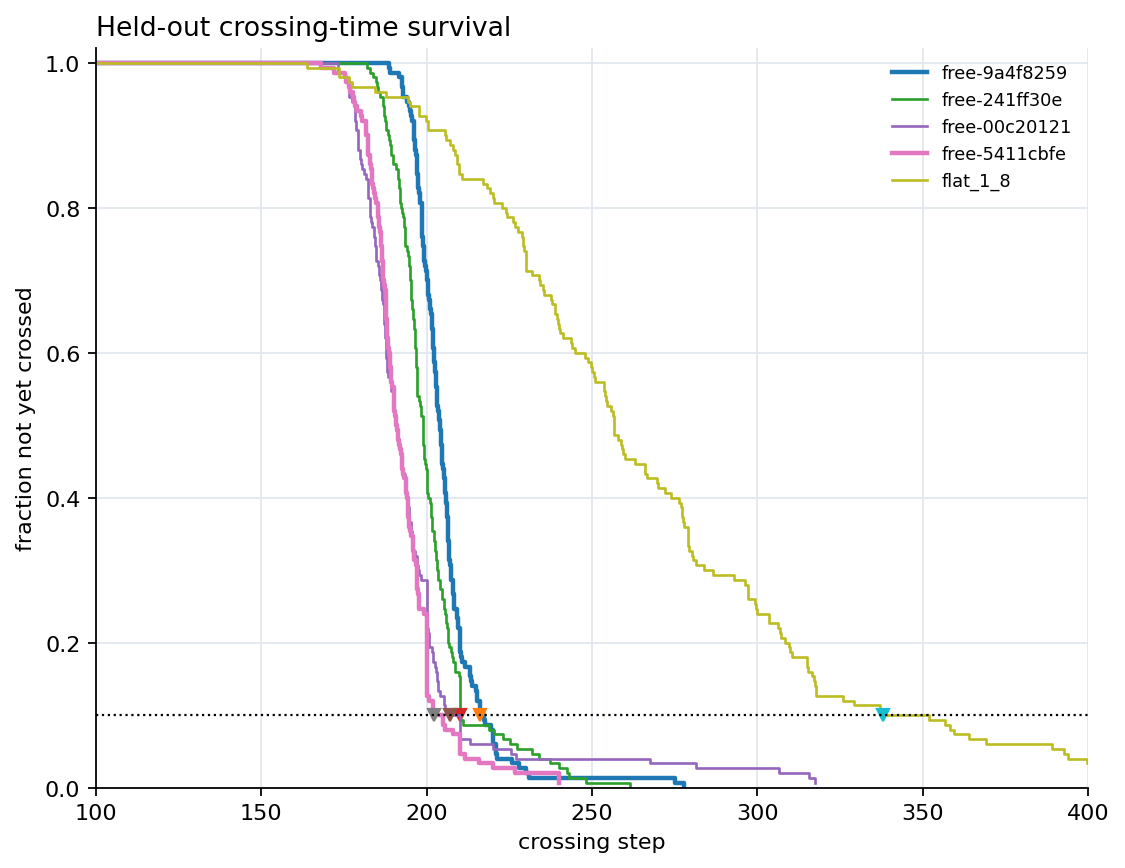
Results — objective: q0.9(T) of unseen_mismatch ≥ 90.5 (censored at B = 400, dwell None)
| arm | q0.9 [CI] | censored | median [CI] | RMST | coverage |
|---|---|---|---|---|---|
| free-5411cbfe | 202.1 [200.0, 210.0] | 0.01 | 190.7 [188.9, 193.7] | 193.9 [191.3, 197.7] | 0.993 |
| free-00c20121 | 207.0 [203.0, 213.0] | 0.01 | 190.7 [188.0, 193.4] | 196.5 [192.6, 201.1] | 0.993 |
| free-c667dd31 | 207.0 [200.3, 215.5] | 0.00 | 189.4 [187.8, 190.3] | 192.8 [190.5, 195.3] | 1.000 |
| free-0c31fbbc | 208.6 [201.3, 215.7] | 0.00 | 190.0 [188.4, 191.7] | 194.0 [191.2, 197.0] | 1.000 |
| free-241ff30e | 210.0 [209.7, 225.1] | 0.00 | 198.8 [196.9, 200.0] | 201.2 [199.2, 203.2] | 1.000 |
| free-6217439f | 212.2 [210.0, 226.1] | 0.00 | 198.0 [197.0, 200.0] | 202.2 [199.8, 205.0] | 1.000 |
| free-82f9c620 | 215.3 [210.0, 230.0] | 0.00 | 201.1 [198.2, 203.2] | 204.6 [202.3, 207.3] | 1.000 |
| free-9a4f8259 | 216.2 [213.0, 220.0] | 0.00 | 204.0 [202.4, 205.5] | 205.8 [204.1, 207.7] | 1.000 |
| free-e059ed86 | 217.0 [210.0, 222.4] | 0.00 | 198.4 [197.1, 200.0] | 202.2 [199.9, 204.8] | 1.000 |
| free-f457fa6e | 217.7 [210.0, 229.1] | 0.00 | 199.5 [198.4, 202.4] | 203.4 [201.4, 205.7] | 1.000 |
| free-d56d6dda | 220.0 [213.0, 229.0] | 0.00 | 202.7 [200.0, 204.9] | 205.8 [203.5, 208.1] | 1.000 |
| phi4star | 230.0 [224.0, 247.8] | 0.00 | 213.9 [209.1, 217.1] | 207.2 [202.3, 212.1] | 1.000 |
| phi3star | 285.0 [280.0, 289.4] | 0.00 | 260.0 [256.0, 263.3] | 252.9 [247.6, 258.0] | 1.000 |
| cand3 | 331.4 [320.6, 339.4] | 0.01 | 303.5 [295.4, 306.4] | 294.4 [288.2, 300.6] | 0.993 |
| flat_1_8 | 337.9 [316.7, 369.3] | 0.03 | 256.7 [249.7, 269.8] | 266.7 [258.0, 275.6] | 0.967 |
| ascend3 | 350.0 [314.5, 399.4] | 0.09 | 248.7 [241.4, 257.5] | 264.2 [255.2, 274.1] | 0.913 |
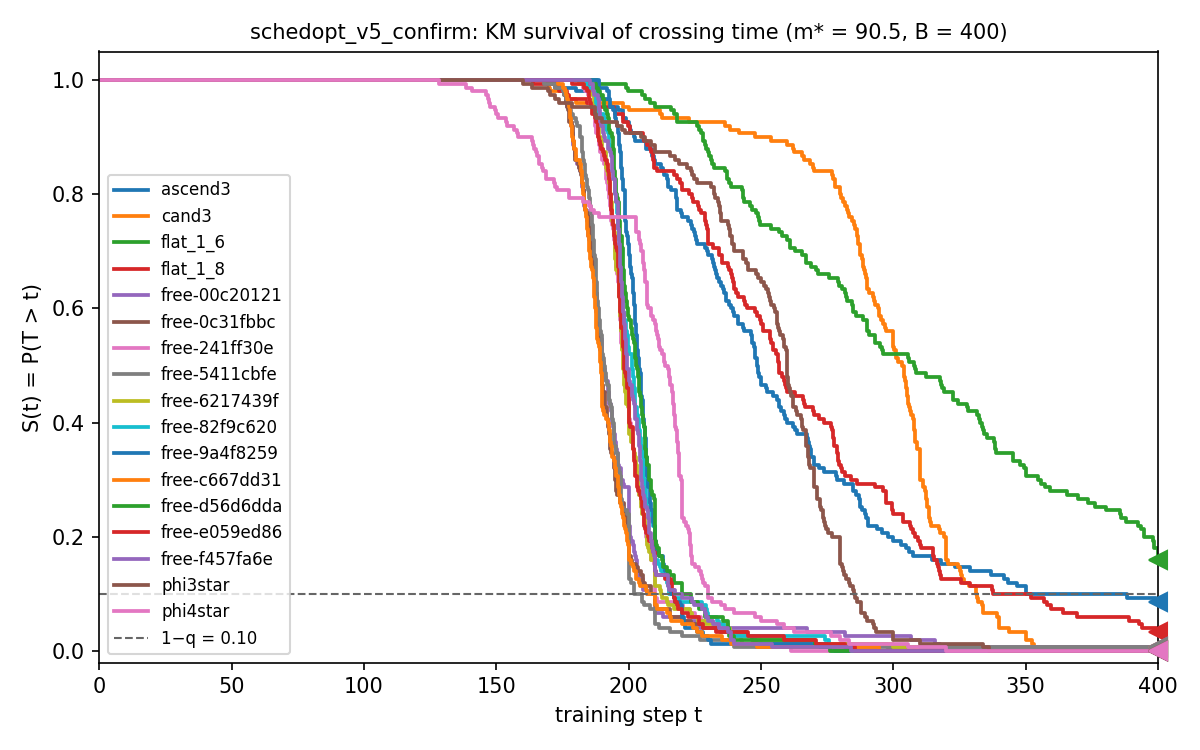
| flat_1_6 | n.i. (censoring 0.16 > 0.10) | 0.16 | 307.9 [288.5, 328.2] | 311.2 [300.8, 321.3] | 0.840 |
Trajectory summary — unseen_mismatch
Evaluation data: seen_* probed at reference α = 1.4 · unseen_* = held-out pairings, uniform (α-independent) · 1000 pairs per condition
- Each probe is a minimal pair: a grammatical sentence and its verb-number-flipped twin. The model scores correct when it assigns the grammatical version higher probability; accuracy = % correct over 1000 pairs per condition.
- seen_match / seen_mismatch — noun–verb pairings that occur in training, sampled at fixed reference α = 1.4 (not at the schedule's own α, so arms stay comparable)
- unseen_match / unseen_mismatch — held-out noun–verb pairings that never occur in training, sampled uniformly (α = 0), so their difficulty is identical across all arms and training αs
- match vs mismatch — whether the prepositional objects agree in number with the subject; mismatch places attractor nouns between subject and verb (the AGREE-RECENT trap)
| arm | end of training (t = 400) | per-seed | flags |
|---|---|---|---|
| ascend3 | 77.9 ±12.8 | ⚠ seed_split: range 45.2-90.8 (2 low / 7 high of 14) | |
| cand3 | 73.1 ±0.0 | ||
| flat_1_6 | 71.4 ±22.3 | ⚠ seed_split: range 18.6-99.8 (2 low / 11 high of 34) | |
| flat_1_8 | 80.4 ±13.9 | ⚠ seed_split: range 51.5-92.6 (1 low / 5 high of 8) | |
| free-00c20121 | 88.0 ±0.0 | ||
| free-0c31fbbc | 92.5 ±0.0 | ||
| free-241ff30e | 93.4 ±0.0 | ||
| free-5411cbfe | 55.3 ±0.0 | ||
| free-6217439f | 92.6 ±0.0 | ||
| free-82f9c620 | 96.8 ±1.4 | ||
| free-9a4f8259 | 95.5 ±2.6 | ||
| free-c667dd31 | 96.3 ±0.0 | ||
| free-d56d6dda | 98.0 ±2.4 | ||
| free-e059ed86 | 94.8 ±2.8 | ||
| free-f457fa6e | 97.2 ±0.0 | ||
| phi3star | 91.9 ±0.7 | ||
| phi4star | 94.5 ±0.0 |
Conclusions
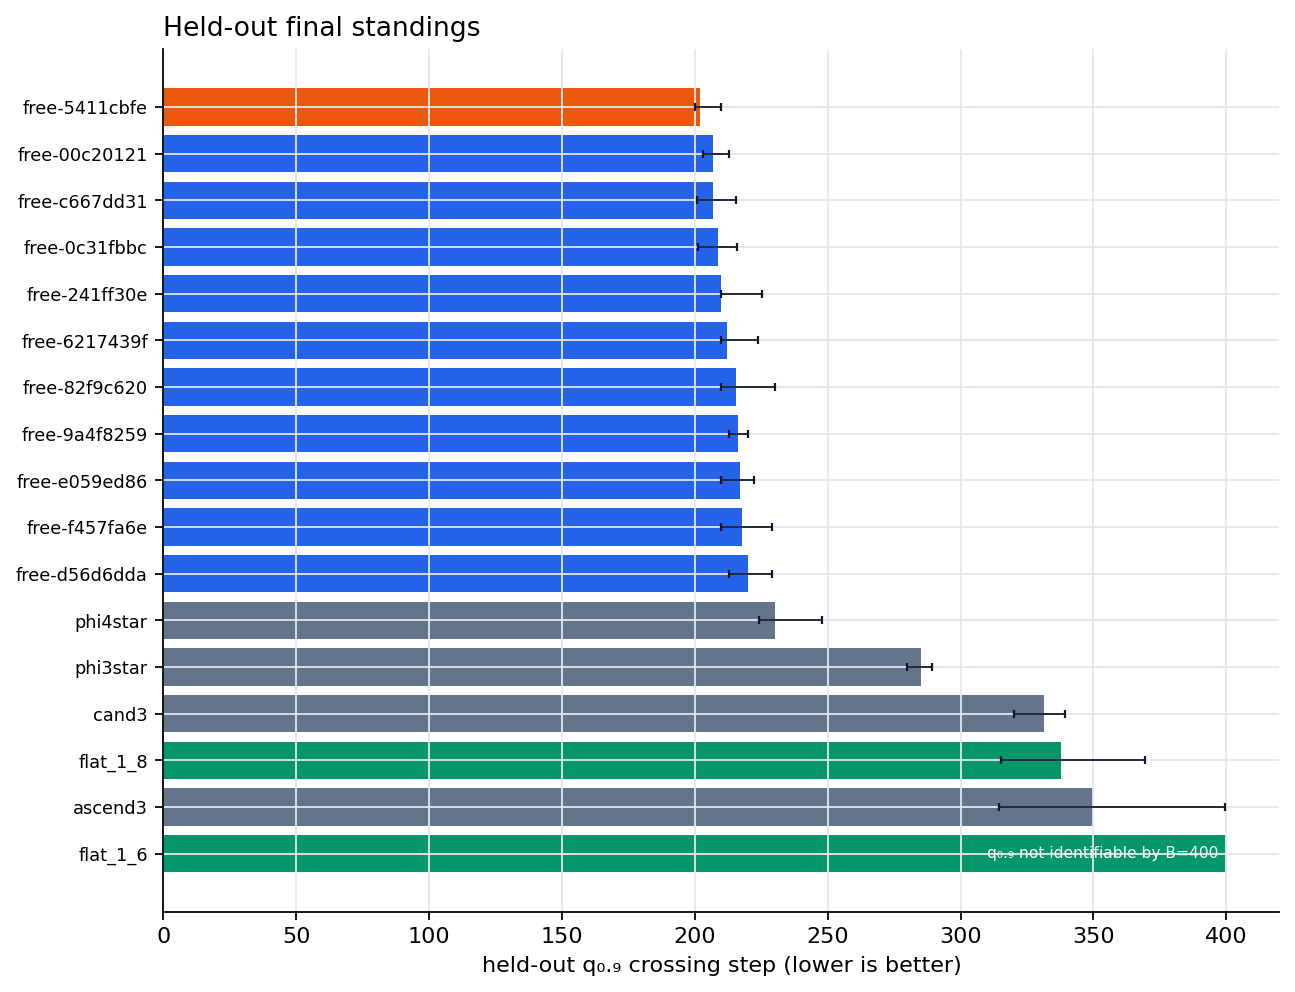
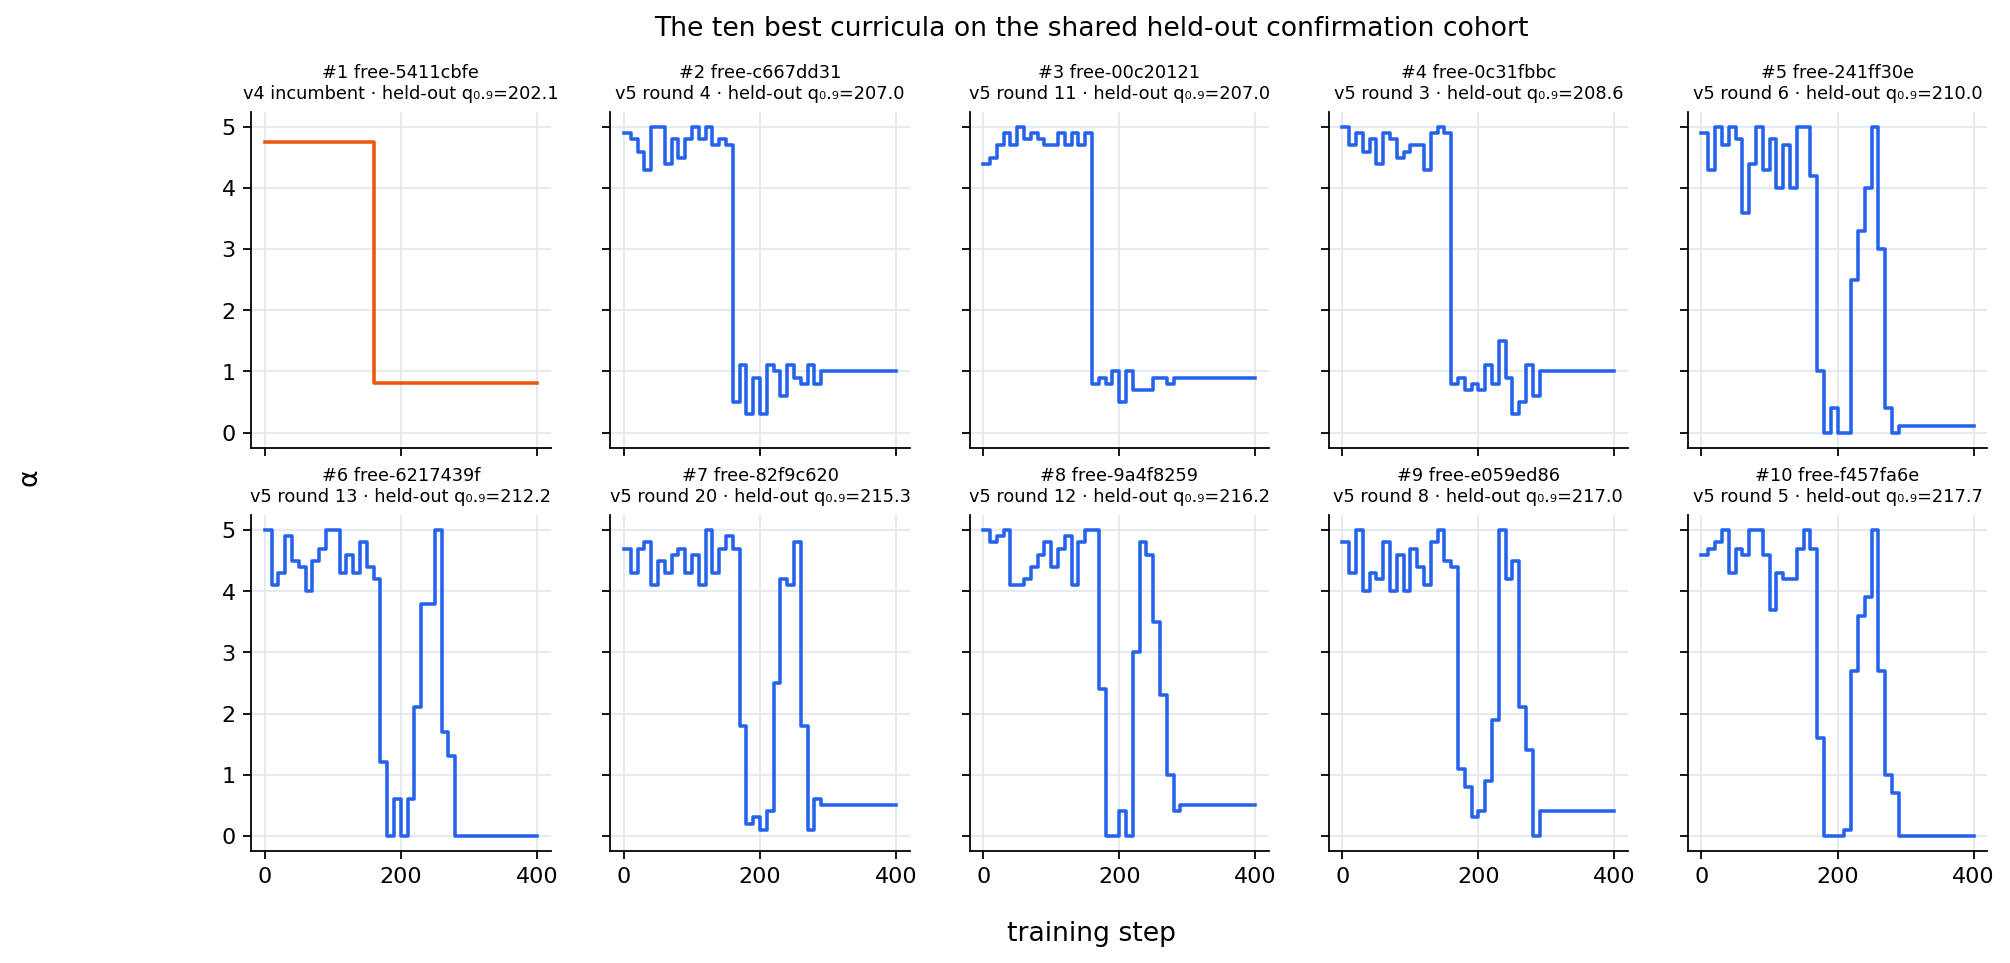
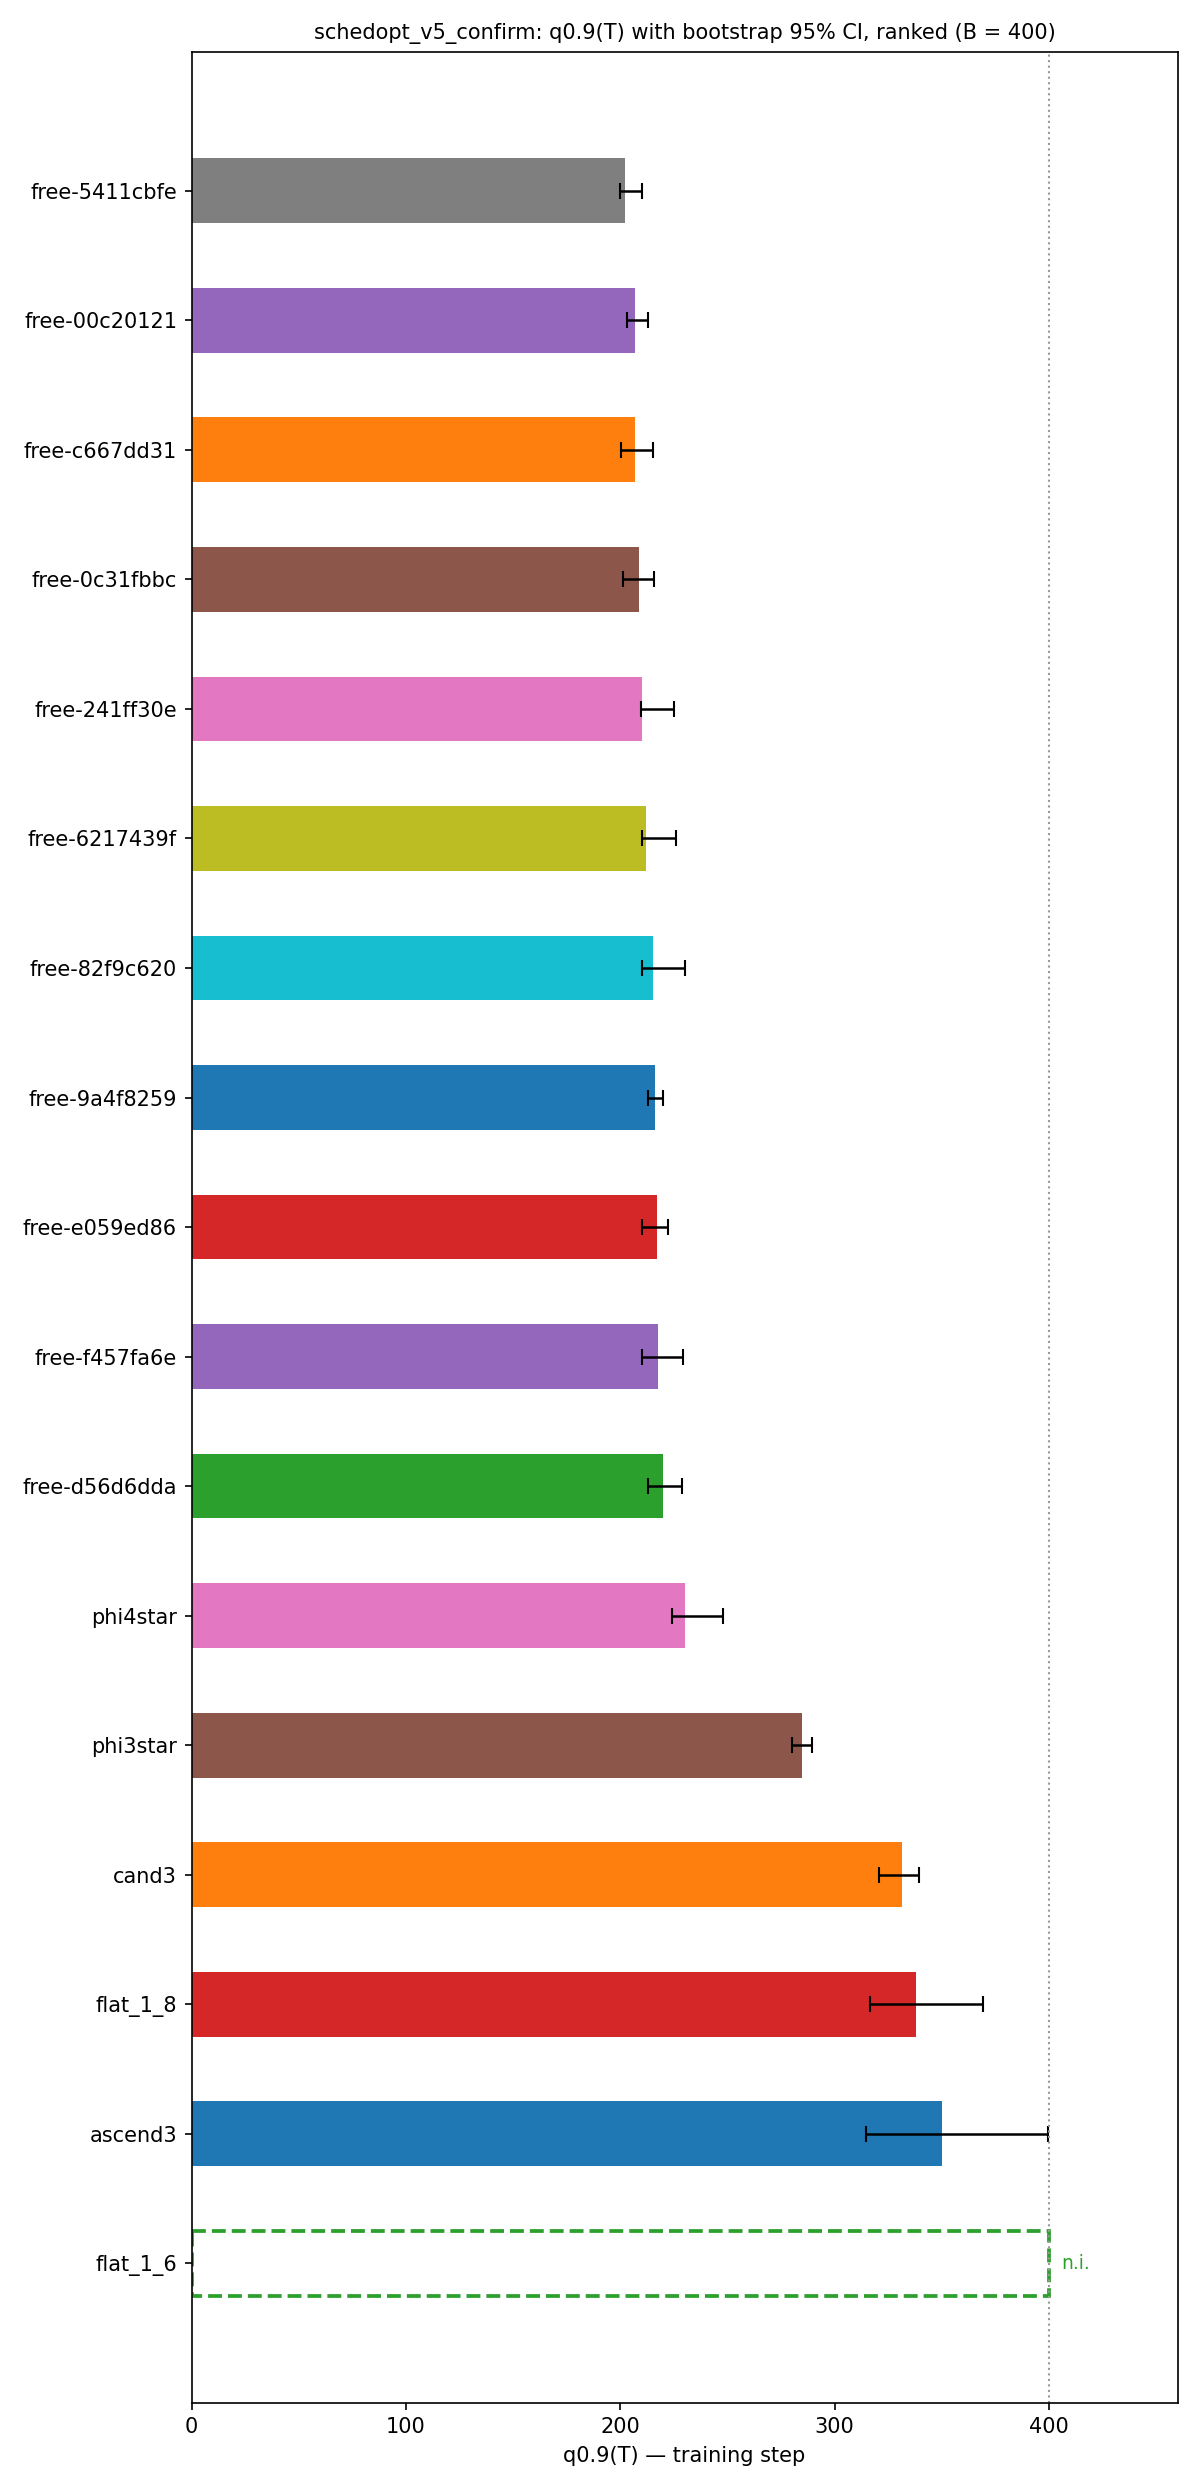
The pre-registered expectation is rejected. On one fresh cohort of 150 seeds that all seventeen arms share, the schedule the search selected reaches the band later than the schedule it was built to beat, and the confirmation puts the incumbent at the top of the field. What survives is the older and larger result: a shaped schedule of α reaches the band far sooner than any constant one.
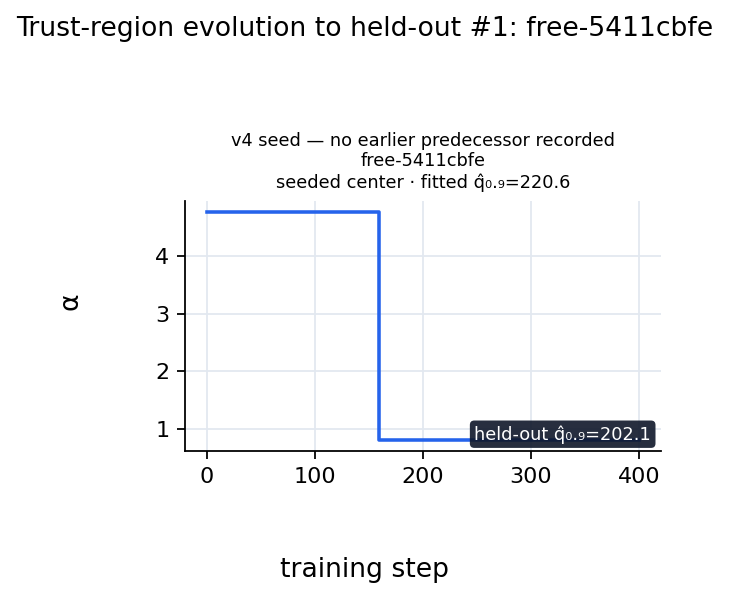
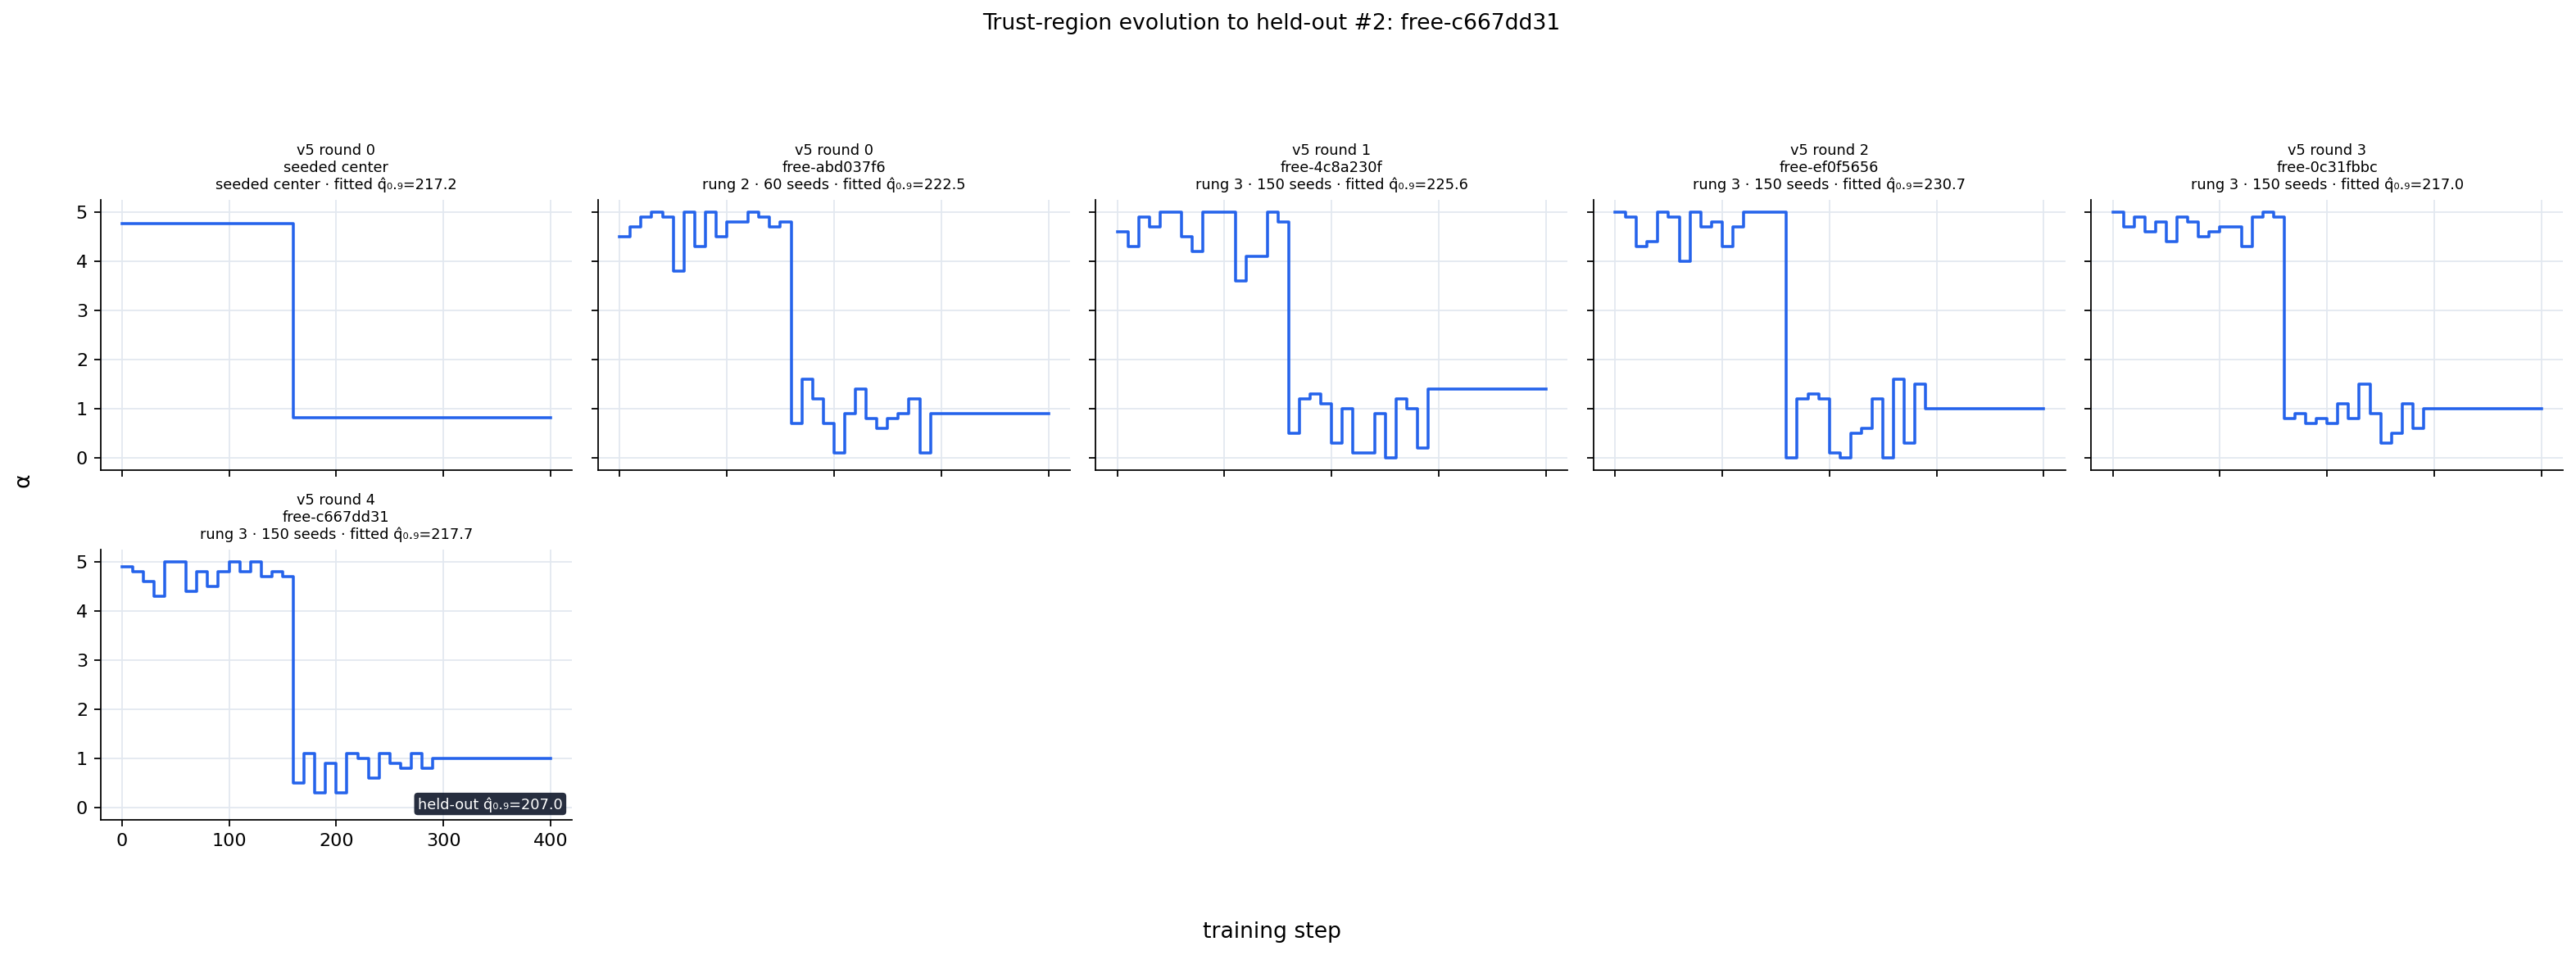
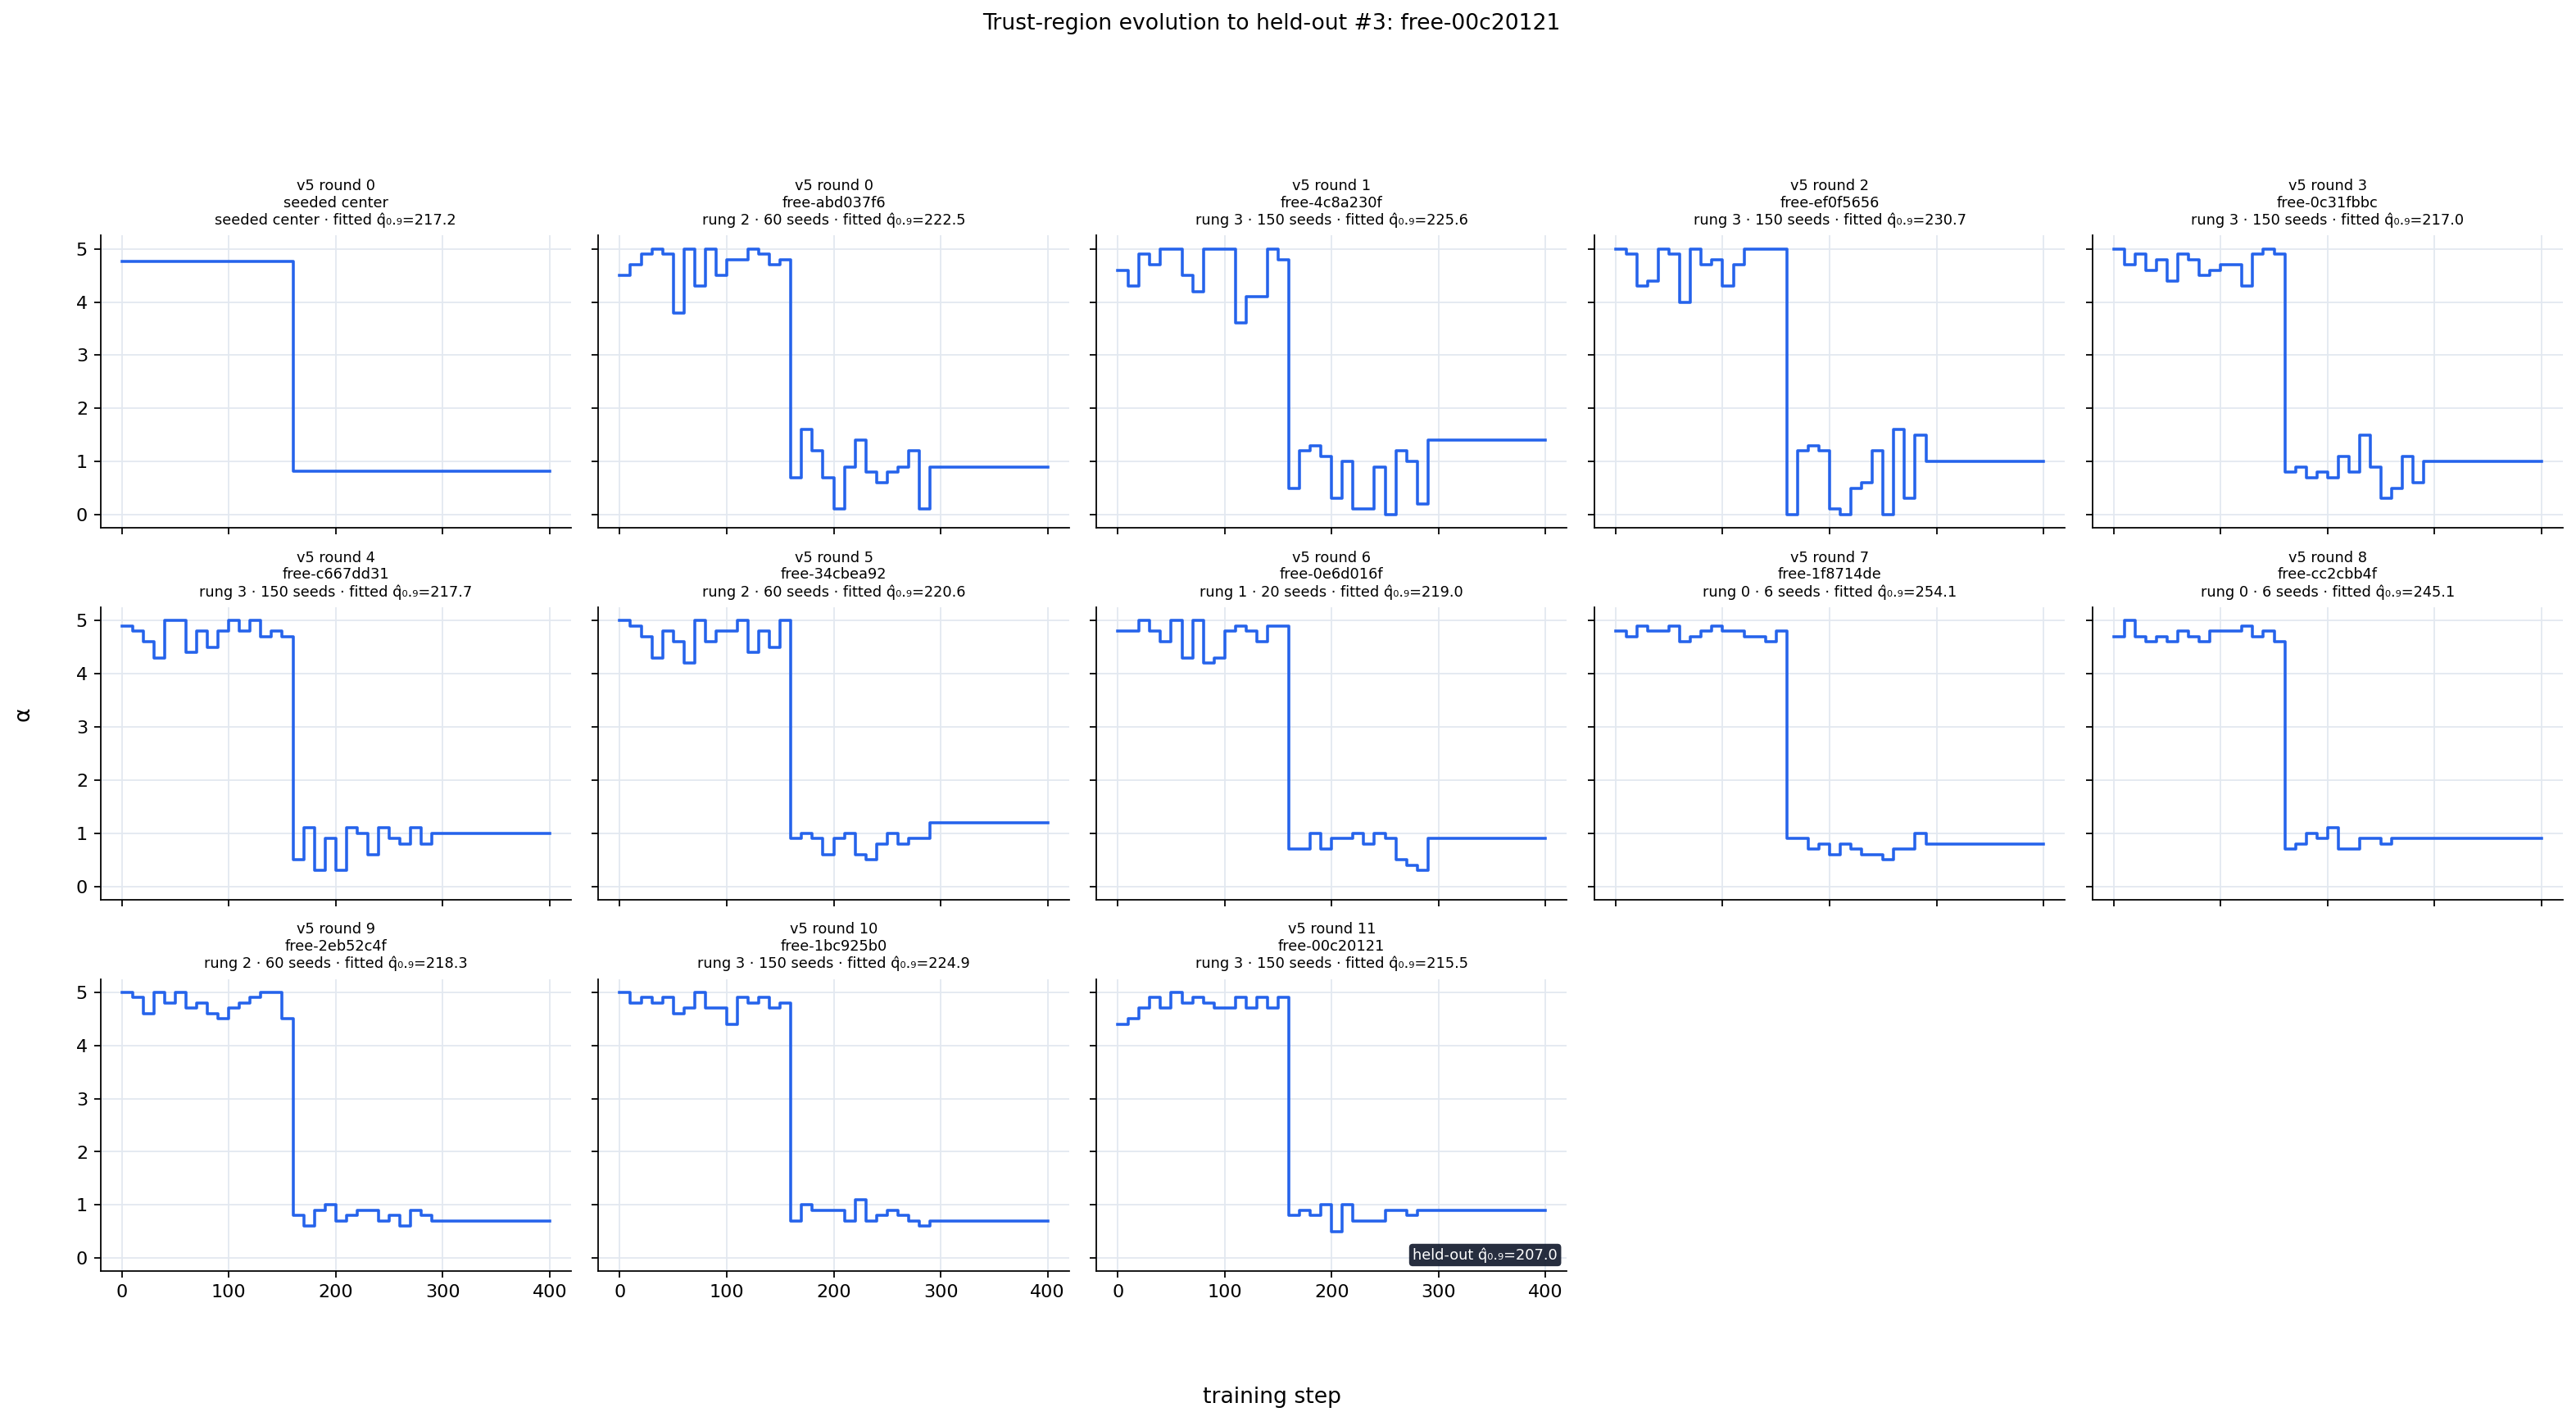
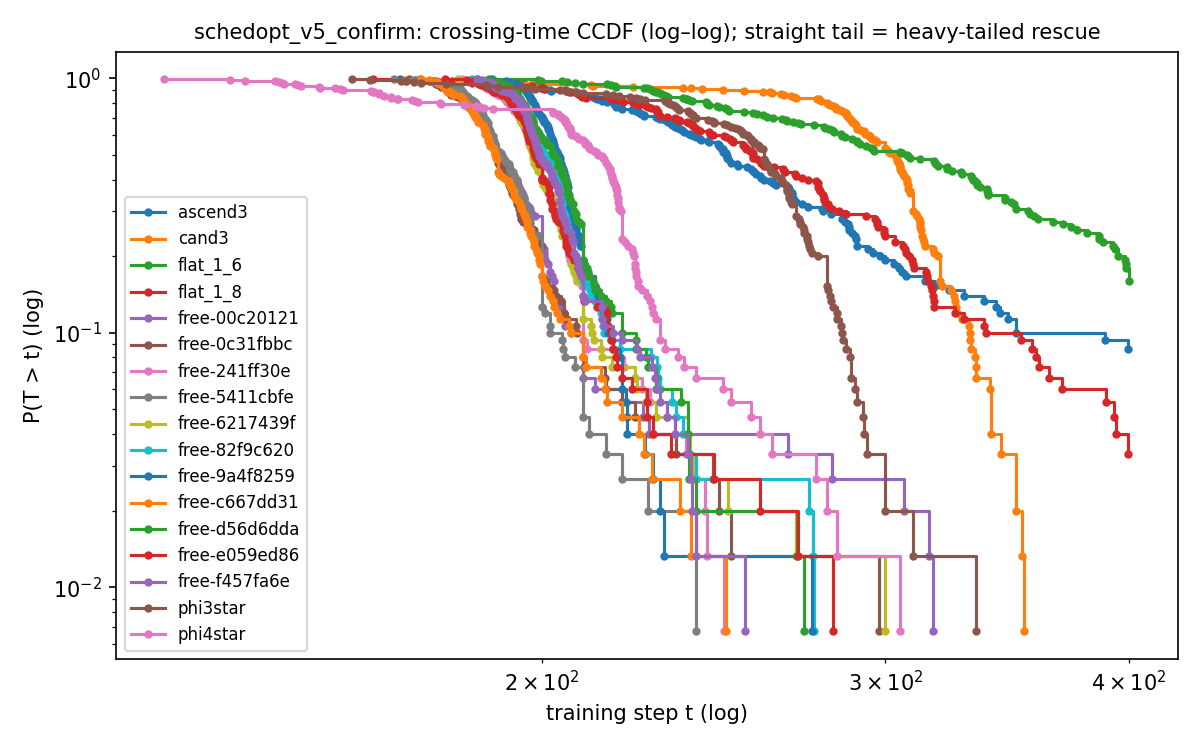
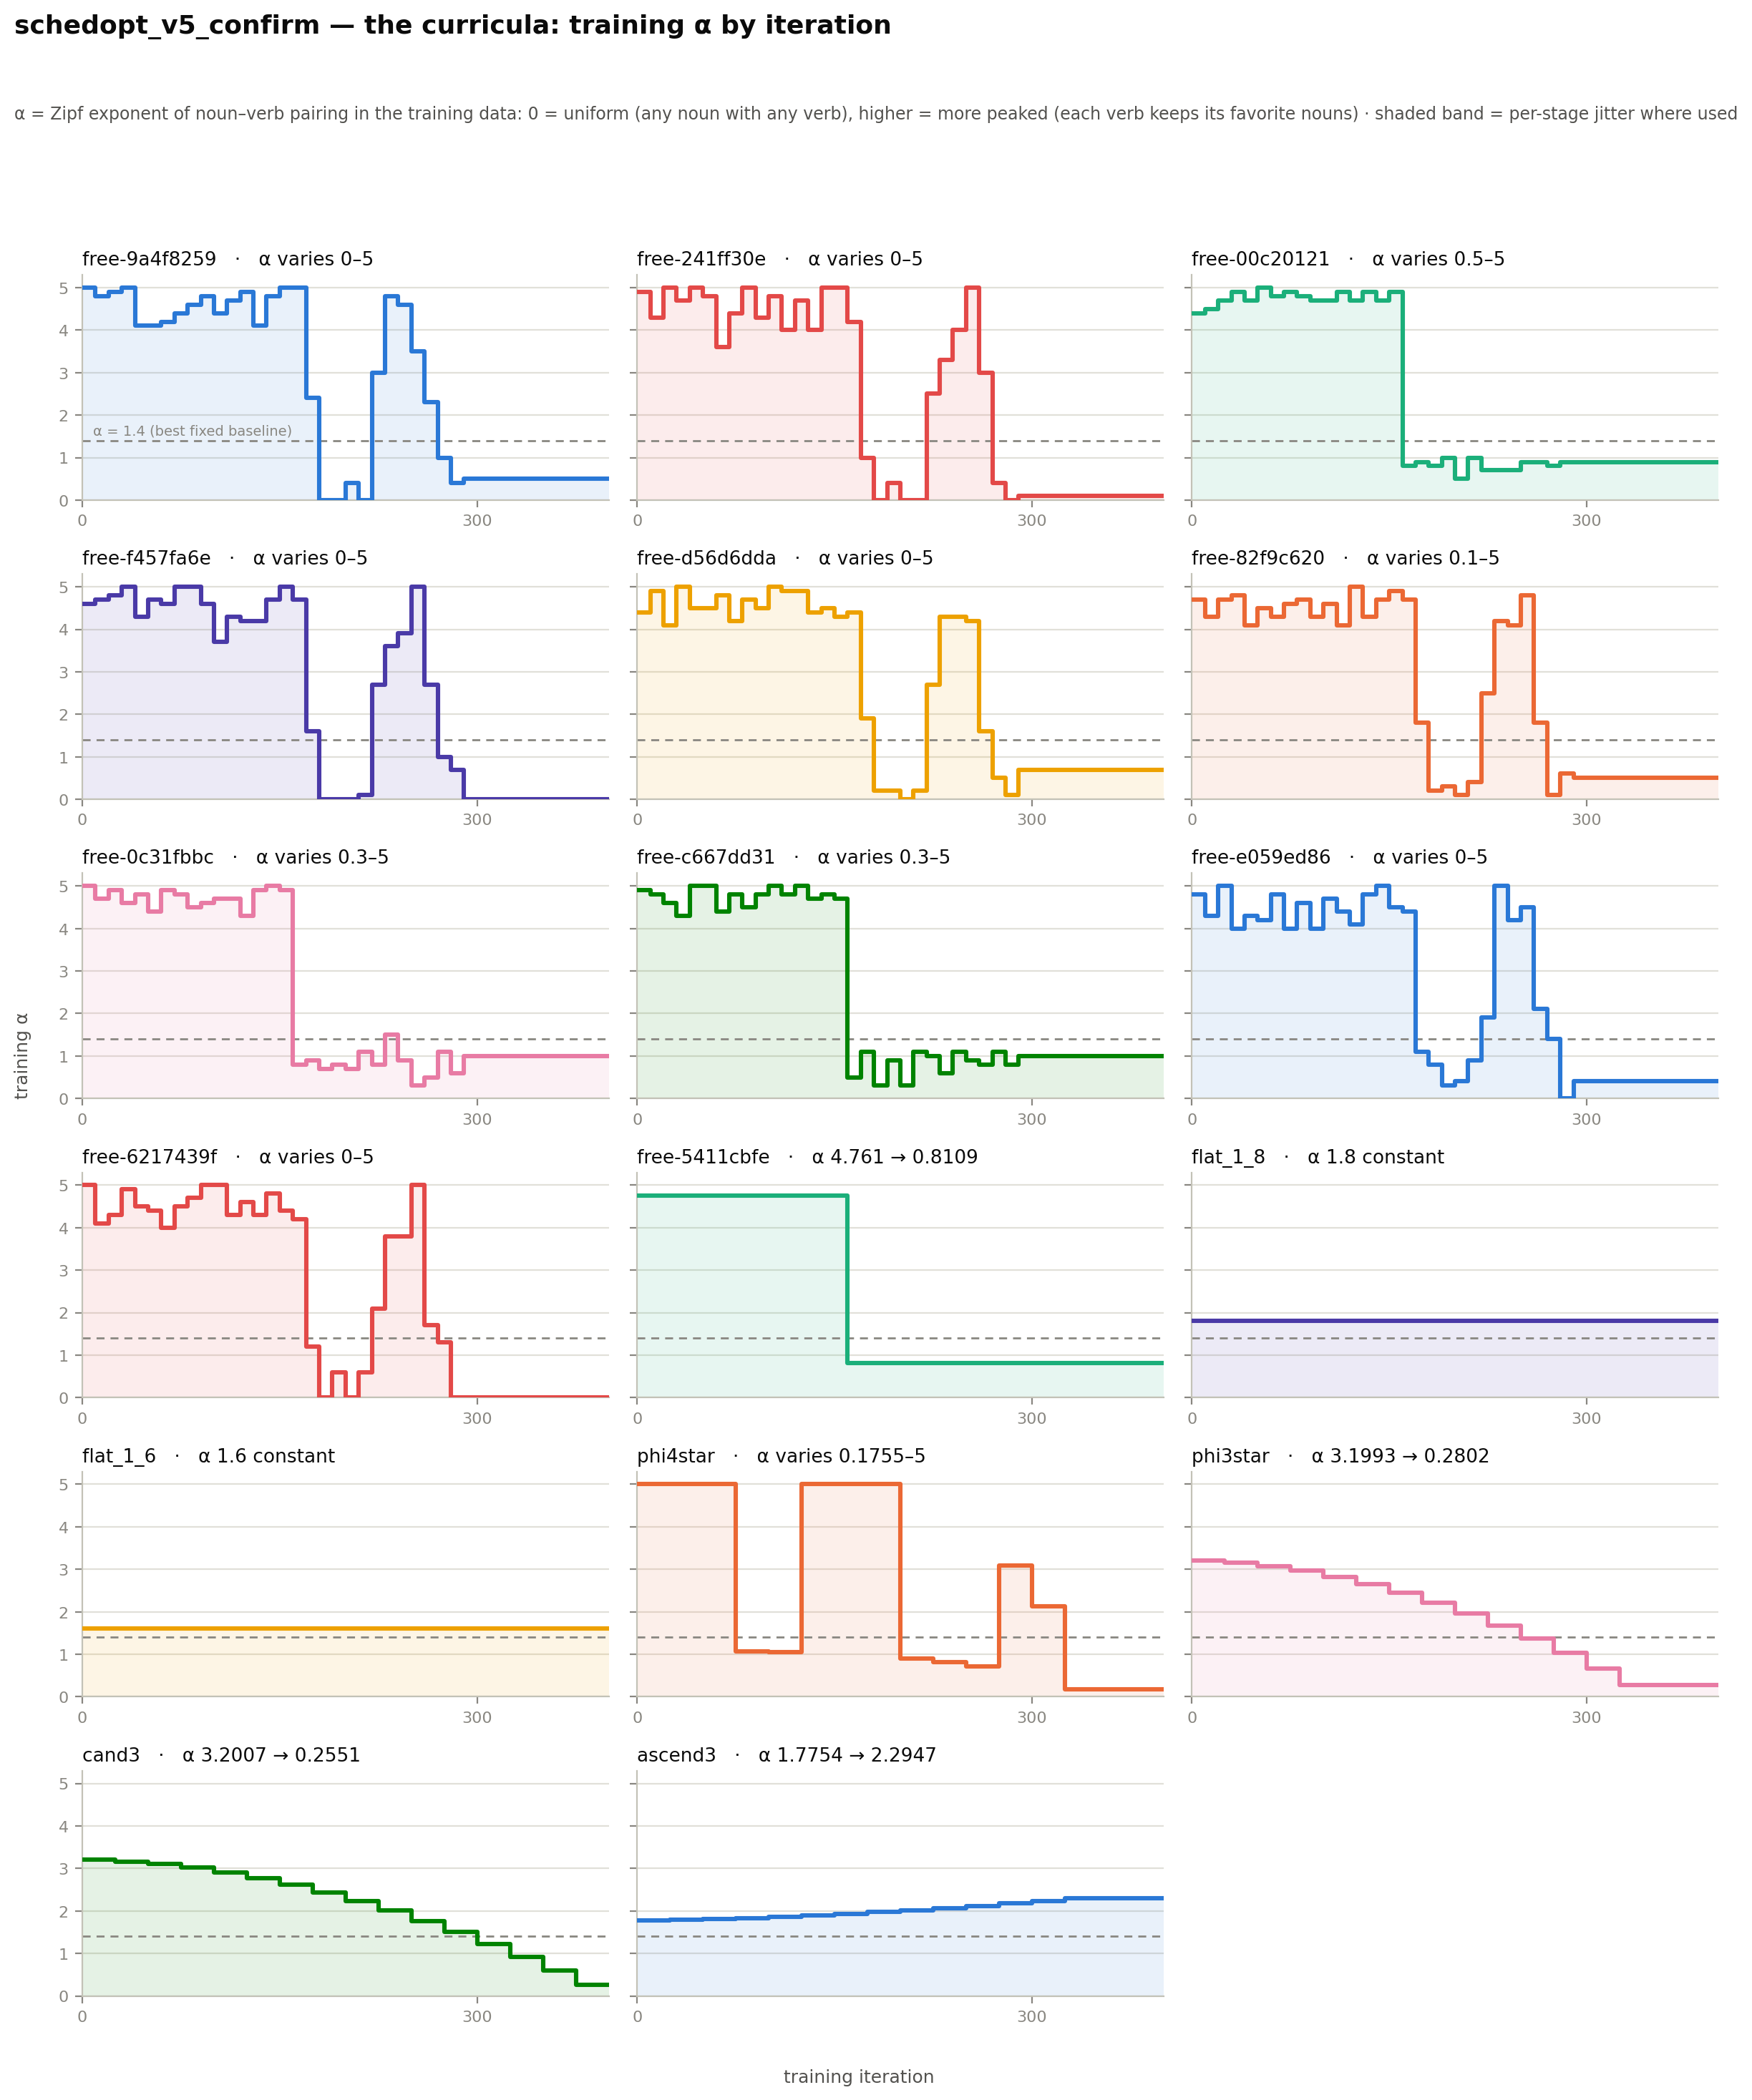
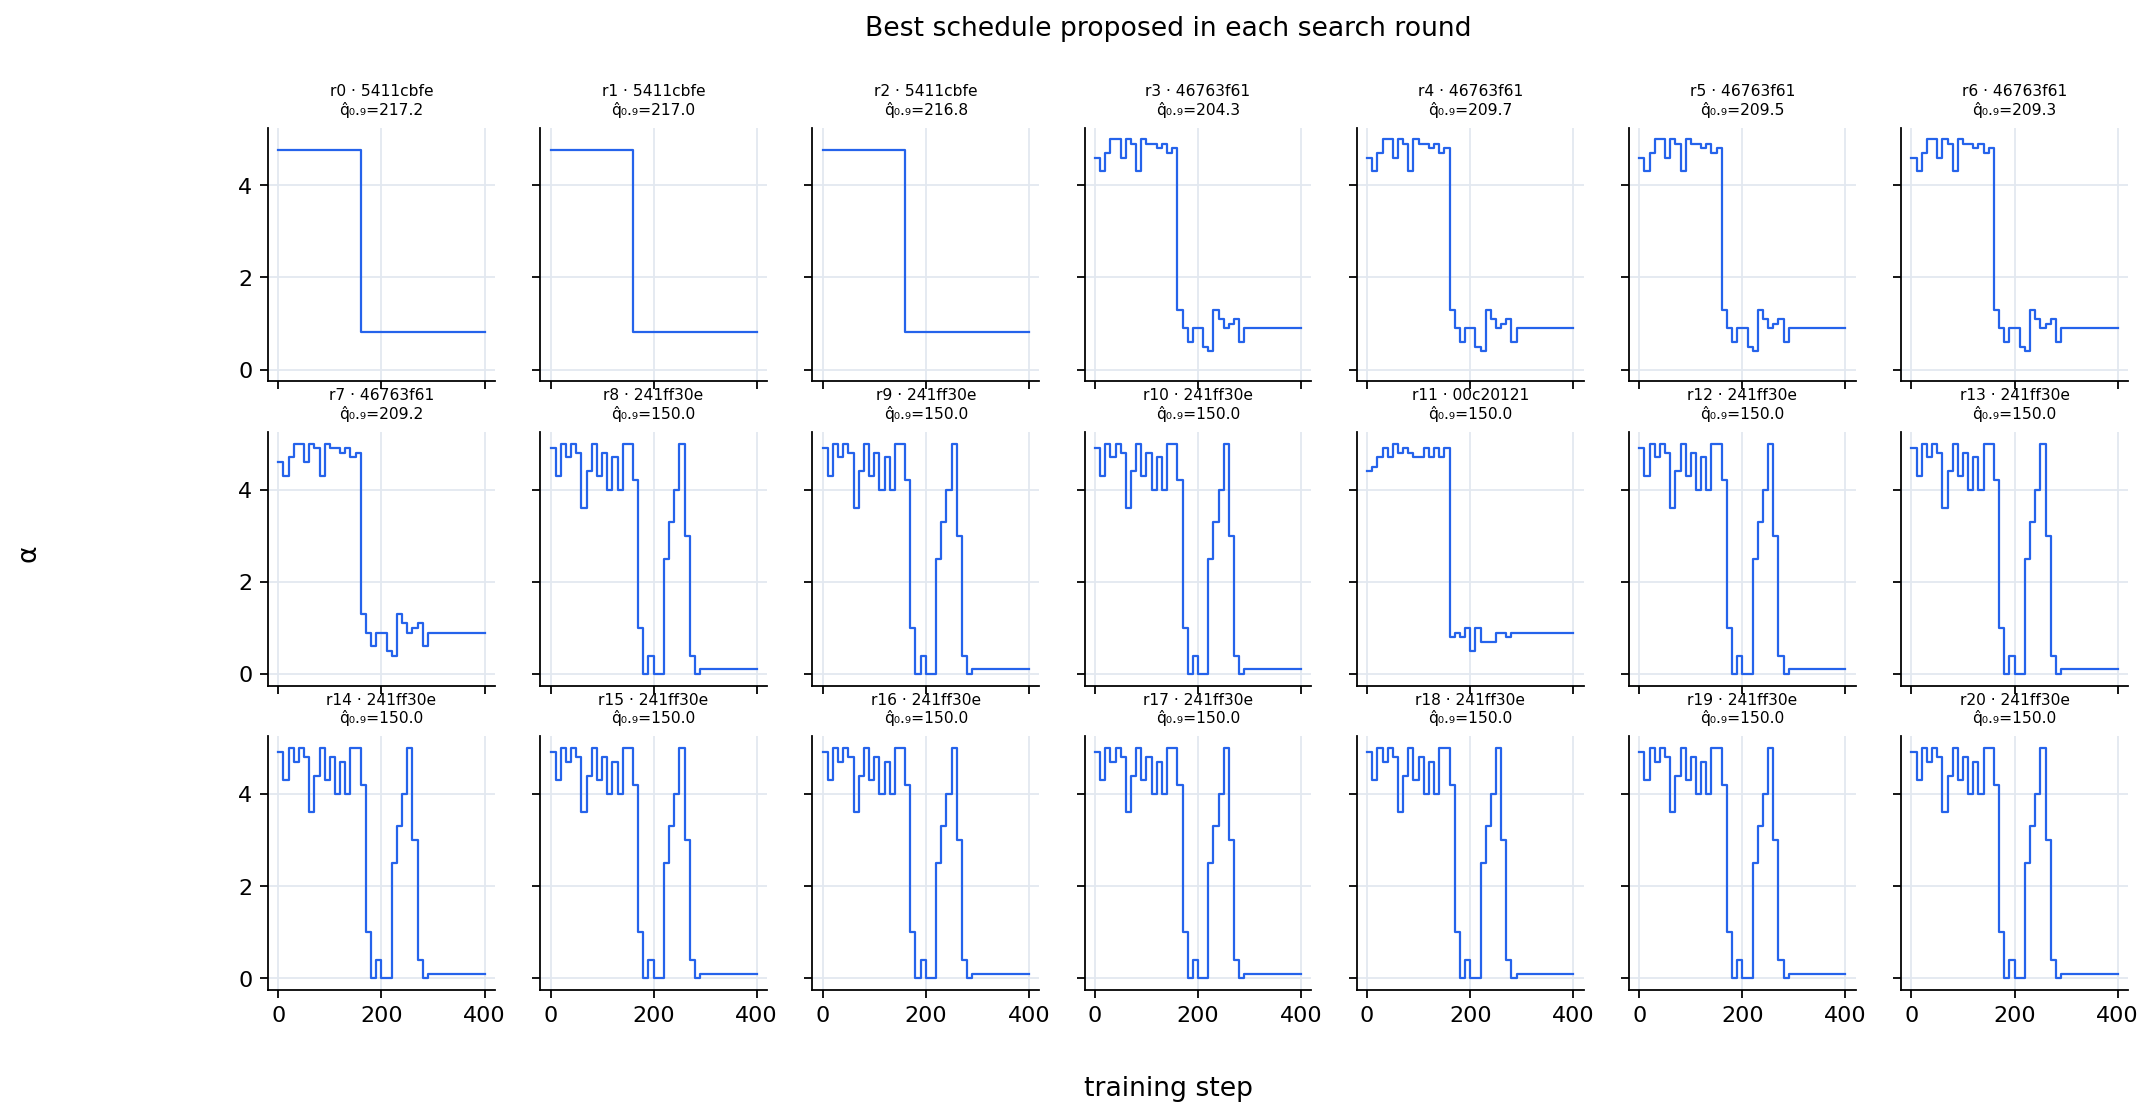
free-5411cbfe, the single-step schedule the previous round found (schedopt_v4), reaches the band at a 90th percentile of 202.1 steps, with a median of 190.7 and one seed in 150 not crossing inside the 400-step budget. The arm this round nominated, free-9a4f8259, reaches 216.2, which is 14.1 steps behind on the paired per-seed comparison (95% interval +5.2 to +20.0). Three other v5 arms land between the two, at 207.0 (free-00c20121 and free-c667dd31) and 208.6 (free-0c31fbbc). Each of those three sits 4.9 to 6.5 steps behind the incumbent with a paired interval that includes zero, computed the same way as the registered headline, so they match it rather than beat it. Nothing measured here is faster than the schedule the round started from.
Referenced by (1 direct, 1 transitive)
Direct references:
Transitive (depth 1):
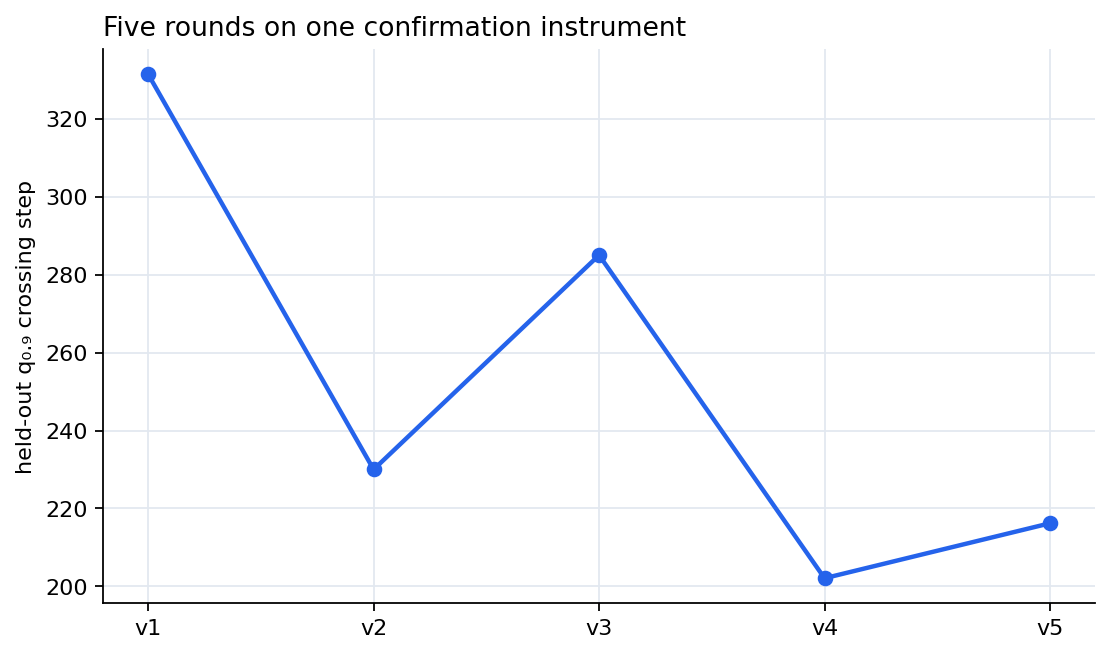
The better constant α, flat_1_8, reaches the band at 337.9 steps, and the nominated schedule clears it by a wide margin (Δ −121.7, 95% interval −153.2 to −97.7); the incumbent clears it by 135.8 steps. The other constant, flat_1_6, has no identifiable 90th percentile at all, because 16% of its seeds never cross inside the budget. Read against the earlier rounds' winners on this same instrument, the campaign's progress is monotone up to the previous round and stops there: 331.4 for the v1 descent (cand3), 285.0 and 230.0 for the v2 smooth and toothed arms (phi3star and phi4star), then 202.1.
Referenced by (2 direct, 2 transitive)
Direct references:
Transitive (depth 1):
Transitive (depth 2):
The mechanism the round pre-registered is half present. The three fastest finalists do cross at a later median than the incumbent, by 7.1 steps with an interval of 4.3 to 8.9, which is the trade the tail objective was meant to accept. What does not appear is the compensation: their fitted log-time dispersion differs from the incumbent's by −0.006, with an interval from −0.052 to 0.034 (the variance thesis). A schedule that crosses later without crossing more consistently is simply slower, which is what the standings show.
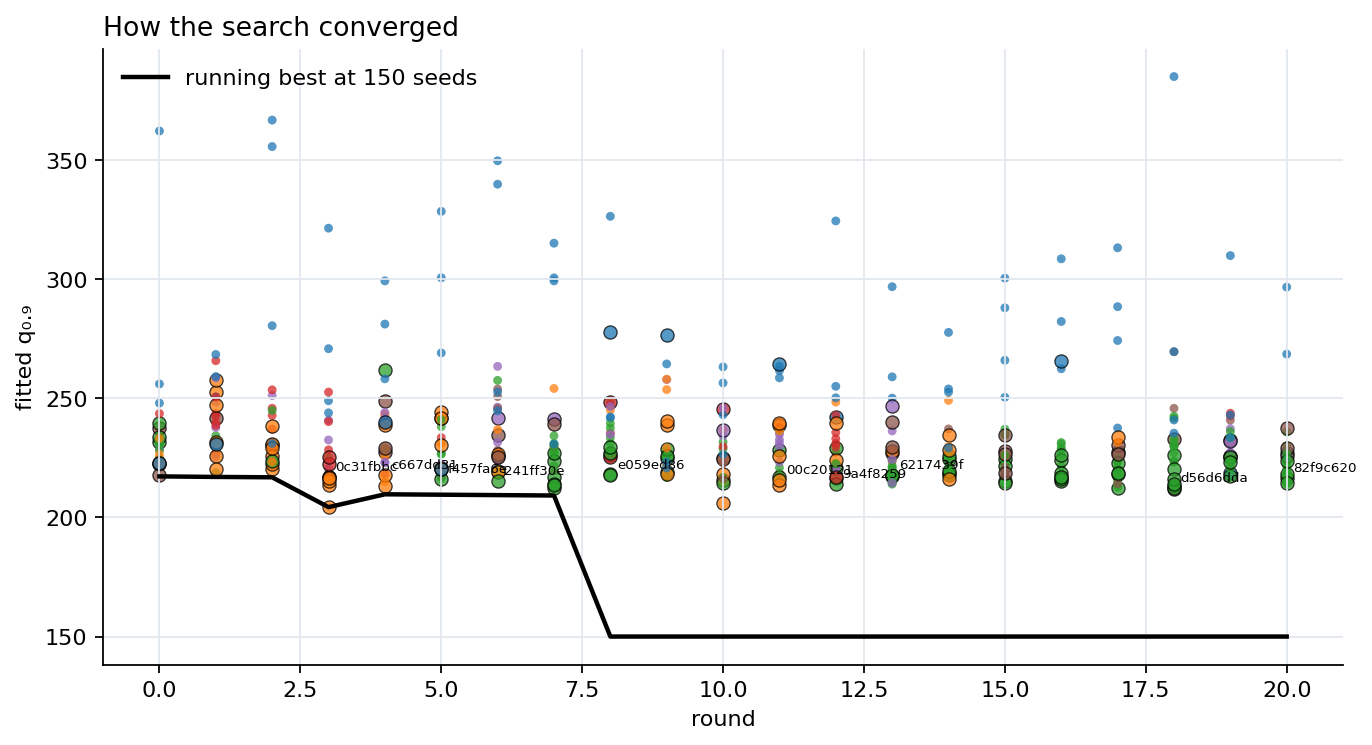
The fourth registered claim, that the finalists would regress against their search-stage numbers, is not informative as it was written. It compares this cohort's Kaplan-Meier quantile against the search's fitted lognormal quantile, which are two different estimators of the same quantity: over the candidates the search measured at full depth the fitted value runs a mean 8.8 steps above the Kaplan-Meier one. The registered reading of −3.8 (the winner's curse claim) is mostly that offset. Compared like against like, this cohort's Kaplan-Meier quantile against the search cohort's, the ten finalists regress by 2.2 steps on average, with an interval from −1.4 to 9.3: a selection effect in the predicted direction and small enough that it explains none of the 14.1-step gap above.
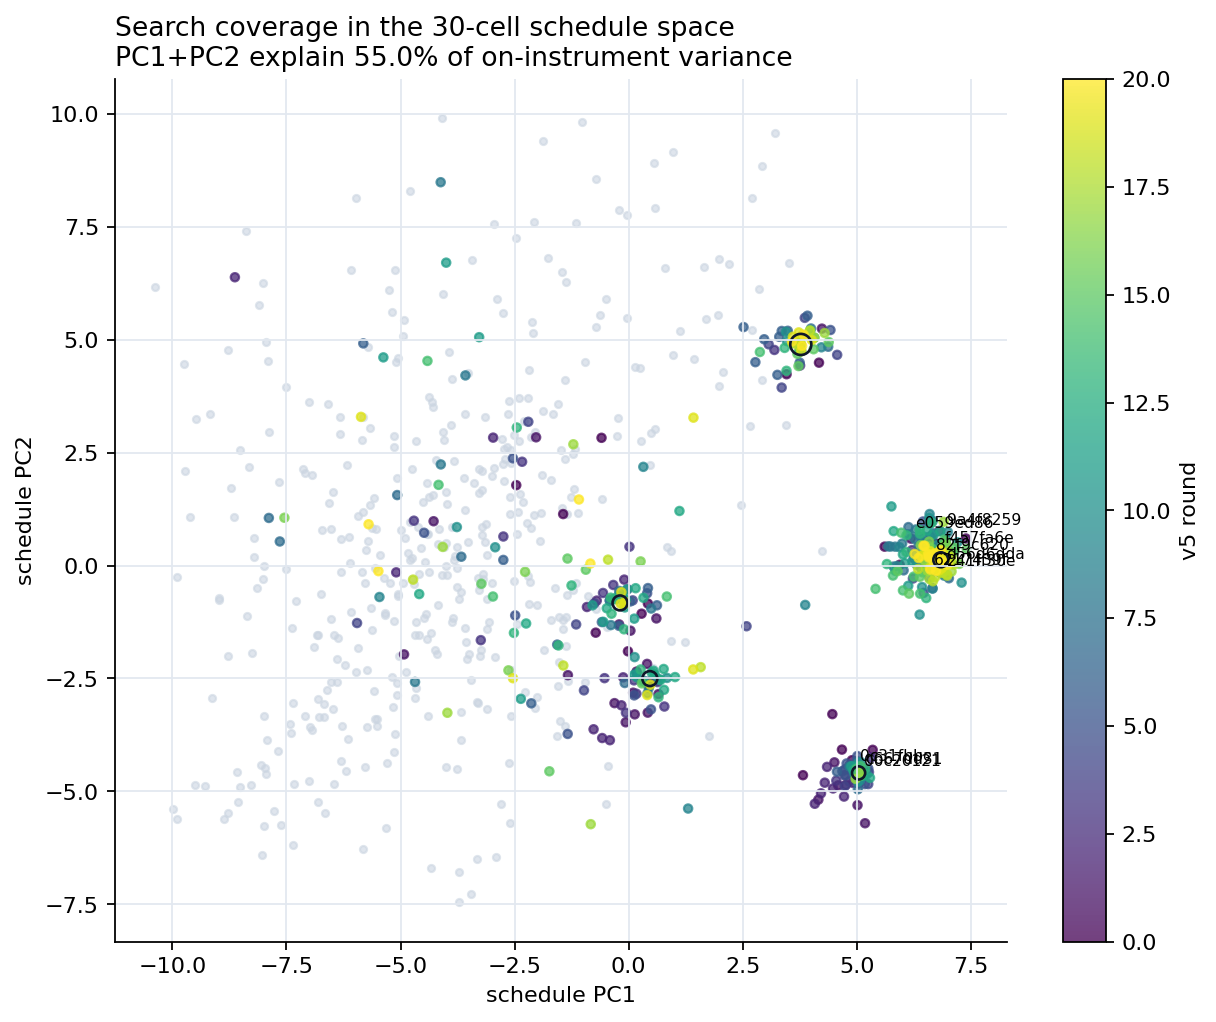
Two things follow for the campaign rather than for this run. The schedules that tie the incumbent here were selected on a quantity that disagrees with the one reported, which is where the next round's attention belongs and is taken up with the search itself (the estimator mismatch). And the incumbent's advantage, which the previous round could not separate from the selection that found it, is now measured on seeds that took no part in choosing it: 198.9 in the search that found it, 202.1 here.
Comparison figures
Children
| Child | peak unseen_mismatch | Status |
|---|---|---|
| free-9a4f8259 | 95.5 | done |
| free-241ff30e | 93.4 | done |
| free-00c20121 | 90.8 | done |
| free-f457fa6e | 97.2 | done |
| free-d56d6dda | 98.0 | done |
| free-82f9c620 | 96.8 | done |
| free-0c31fbbc | 92.5 | done |
| free-c667dd31 | 96.3 | done |
| free-e059ed86 | 94.8 | done |
| free-6217439f | 92.6 | done |
| free-5411cbfe | 93.5 | done |
| flat_1_8 | 80.4 | done |
| flat_1_6 | 71.4 | done |
| phi4star | 94.5 | done |
| phi3star | 93.1 | done |
| cand3 | 91.6 | done |
| ascend3 | 81.5 | done |